I worked on this for more than 2 days. Originally I expected to fit it comfortably into 1 day, but so many problems and complications came up that I am glad it only took 2.25 days. On day 1 I removed hidden images from the HTML of the blog posts wherever they were not needed in the article. (I used to add hidden images so that they would not be visible in the post itself, but such a hidden image did show up in the list of articles, and when no image, hidden or not, was available, my Aurora theme displayed a placeholder.) I did this so those images would not get downloaded, because from the very beginning I had everything planned out: export the posts from Blogger, run all of them through my own tool BlogConverter, replace the image links in <a href="..."> or <img src="..."> in the exported file with addresses on the blog.sunamo.cz domain, convert that file into the WordPress export format and import it into this blog, blog.sunamo.cz.
Anyway, whether a post had a (non-)hidden image or not, I saved it to disk under the name of the blog post. Then I imported the export file into WP, added a featured image to every post for which I had an image on disk, and thought I was done. Oops, that was only an illusion and the beginning of my troubles.
While going through some of the posts, I found that in places I had empty yet multi-line <pre> tags. I am not sure exactly what caused it, but only one explanation comes to mind: the content of the <pre> tag simply was not HTML encoded. This affected pretty much every <pre> tag, mostly those with XML/HTML content, but also, for example, C# where I worked with generics. On the second day I was fixing all of it by hand, because the verbose Blogger export file wanted HTML entities as &lt; in some places and as < in others.
So whenever I converted, say, < to &lt;, everything fell apart, and I spent the second day carving out the template and doing the rest by hand. In the evening, at 8 p.m., I decided that I would never finish it this way and downloaded a clean Blogger template again. The next morning I quickly wrote code that treated the export as a plain string rather than as HTML via HtmlAgilityPack, because I could not do replacements in it and HAP kept mangling the code in all sorts of ways.
On top of that, what kept slowing me down on day 2 was that I had to compile and run the program, then click a button to say I had a Blogger export file, choose Load from the menu, click the Downloads folder, select the file and only then click to have it processed. During those 2 days I also had to deal with smaller issues and requirements, such as keeping posts with Windows 8 Apps Control in the title out of the WP export file, since all 44 of those posts will now live on my website. First, though, I will have to clean up my SSD, because if I do not, it will probably die on me soon. Here you can see how much space is used on the SSD with the OS and on the classic HDD with data:
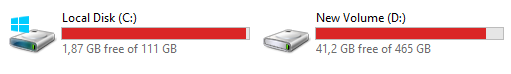
I also did not realize at the start that I needed links to the larger images as well. So I added that later, so that the images under <a href="..."> would also be downloaded and the href attribute replaced to point to my hosting for the blog. To wrap up, the new approach turned out to be not only the easiest, but also the right one, and I was really happy when I uploaded the export with the old blog (1222 posts) and everything was exactly as it should be. If you would like to see what the whole method I used to convert the blogs looked like, here it is:
public void cmdDownloadAllImages_Executed(object sender, ExecutedRoutedEventArgs e)
{
OpenBlogExport(BlogService.Blogger, @"C:\Users\Radeksunamo\Downloads\jepsano-11-27-2014-tak znovu.xml");
int seriesNumber = 0;
string targetFolder = Path.Combine(FA.GetFolder(AppFolders.Data), fromBlogService + "Images" + seriesNumber.ToString());
while (Directory.Exists(targetFolder))
{
seriesNumber++;
targetFolder = Path.Combine(FA.GetFolder(AppFolders.Data), fromBlogService + "Images" + seriesNumber.ToString());
}
string[] excludeContainingInTitle = new string[] { "Windows 8 Apps Controls"};
int imageNumber = 0;
Directory.CreateDirectory(targetFolder);
WebClient webClient = new WebClient();
string diacriticWithSpaces = "";
Dictionary<string, string> htmlEntityToChar = new Dictionary<string, string>();
StringBuilder stringBuilder = new StringBuilder();
foreach (var item in SH.diacritic)
{
stringBuilder.Append(item.ToString() + " ");
}
diacriticWithSpaces = stringBuilder.ToString();
string entityHtmlWithSpaces = HttpUtility.HtmlEncode(diacriticWithSpaces);
string[] chars = SH.Split(diacriticWithSpaces, " ");
string[] entities = SH.Split(entityHtmlWithSpaces, " ");
if (chars.Length != entities.Length)
{
throw new Exception("Unequal number of arguments.");
}
for (int i = 0; i < chars.Length; i++)
{
htmlEntityToChar.Add(entities[i], chars[i]);
}
List<string> allAnchorDomains = new List<string>();
List<string> allImageDomains = new List<string>();
List<string> allAnchorExtensions = new List<string>();
List<string> allImageExtensions = new List<string>();
//-For all these domains I will download only if it is an image (i.e. it contains .JPG/.jpg/.Jpg etc. + PNG, GIF, JPEG, BMP
List<string> domainsToReplaceAnchor = new List<string>(new string[] { "3.bp.blogspot.com",
"4.bp.blogspot.com",
"1.bp.blogspot.com",
"2.bp.blogspot.com",
"cl.ly",
"lh5.ggpht.com",
"lh3.ggpht.com",
"lh4.ggpht.com",
"lh6.ggpht.com",
"lh5.googleusercontent.com",
"lh3.googleusercontent.com",
"lh4.googleusercontent.com",
"lh6.googleusercontent.com",
"www.talkandroid.com",
"picasaweb.google.com",
//"sunamoblog.blogspot.com",
//"dl.dropbox.com",
"translate.googleusercontent.com"
});
List<string> domainsToReplaceImage = new List<string>(domainsToReplaceAnchor);
Dictionary<string, string> sampleUriByAnchorExtension = new Dictionary<string, string>();
Dictionary<string, string> sampleUriByImageExtension = new Dictionary<string, string>();
var blogPosts = bv.GetAllPostsButExcludeInTitle(excludeContainingInTitle);
var postCount = bv.Posts.Count;
foreach (BloggerPostModel item in blogPosts)
{
string originalContent = item.content.nonVerbose;
List<int> visitedIndexes = new List<int>();
string preStartTag = "<pre class="brush:";
int searchStart = 0;
while (searchStart != -1)
{
int startIndex = originalContent.IndexOf(preStartTag, searchStart);
if(startIndex == -1)
{
searchStart = -1;
break;
}
else
{
searchStart = startIndex + preStartTag.Length;
}
int endIndex = originalContent.IndexOf("</pre", searchStart);
string sub = originalContent.Substring(searchStart + 1, endIndex);
string rep = sub.Replace("<br />", "").Replace("<br/>", "").Replace("<br>", "");
rep = HttpUtility.HtmlDecode(rep);
rep = HttpUtility.HtmlDecode(rep);
originalContent = originalContent.Replace(sub, rep);
}
HtmlParser htmlParser = new HtmlParser();
htmlParser.LoadHtml("<div>" + originalContent + "</div>");
System.Collections.Generic.List<HtmlNode> imgs = htmlParser.ReturnAllTags(htmlParser.DocumentNode, "img");
originalContent = originalContent.Replace("<span id="more-204"></span>", "");
Dictionary<string, string> alreadyReplacedAttributeValues = new Dictionary<string, string>();
foreach (var item2 in imgs)
{
var src = HtmlHelper.GetValueOfAttribute("src", item2);
//-For both blogs on Blogger this printed True
if (src.Trim() != "")
{
src = src.Replace("<br />", "");
if(!alreadyReplacedAttributeValues.ContainsKey(src))
{
}
else
{
//-This should never happen here
continue;
}
Uri uri = null;
try
{
uri = new Uri(src);
}
catch (Exception)
{
Debug.Print("Failed to create a Uri object from the address " + src);
continue;
}
//.Replace("www.", "")
var domainLower = uri.Host.ToLower();
if(!allImageDomains.Contains(domainLower))
{
allImageDomains.Add(domainLower);
}
bool shouldReplaceImageDomain = domainsToReplaceImage.Contains(domainLower);
if (shouldReplaceImageDomain)
{
var lastDotIndex = src.LastIndexOf('.');
var extension = ""; //Path.GetExtension(href);
if (lastDotIndex != -1)
{
int questionMarkIndex = src.LastIndexOf('?');
if (questionMarkIndex != -1 && questionMarkIndex > lastDotIndex)
{
extension = SH.Substring(src, lastDotIndex - 1, questionMarkIndex -1);
}
else
{
extension = src.Substring(lastDotIndex);
}
}
if (extension != "")
{
if(!allImageExtensions.Contains(extension))
{
sampleUriByImageExtension.Add(extension, src);
allImageExtensions.Add(extension);
}
if (domainsToReplaceImage.Contains(domainLower) && SH.ContainsAny(src, ".JPG", ".Jpg", ".jpg", ".PNG", ".Png", ".png", ".JPEG", ".Jpeg", ".jpeg", ".GIF", ".Gif", ".gif", ".BMP", ".Bmp", ".bmp"))
{
string fileNameWithExt = seriesNumber.ToString() + "_" + imageNumber.ToString() + extension;
var http = "http://blog.sunamo.cz/i/" + fileNameWithExt;
string contentBeforeReplace = string.Copy(originalContent);
originalContent = originalContent.Replace(src, http);
alreadyReplacedAttributeValues.Add(src, http);
if (contentBeforeReplace != originalContent)
{
try
{
webClient.DownloadFile(src, Path.Combine(targetFolder, fileNameWithExt));
}
catch (Exception ex)
{
Debug.Print(ex.Message);
}
imageNumber++;
}
}
}
else
{
Debug.Print("Image " + src + " had no extension");
}
}
}
//
}
//-Replace anchors in links (anchors)
imgs = htmlParser.ReturnAllTags(htmlParser.DocumentNode, "a");
foreach (var item2 in imgs)
{
var href = HtmlHelper.GetValueOfAttribute("href", item2);
//-For both blogs on Blogger this printed True
if (href.Trim() != "")
{
bool addToDictionary = false;
href = href.Replace("<br />", "");
if (!alreadyReplacedAttributeValues.ContainsKey(href))
{
}
else
{
continue;
}
Uri uri = null;
try
{
uri = new Uri(href);
}
catch (Exception)
{
Debug.Print("Failed to create a Uri object from the address " + href);
continue;
}
//.Replace("www.", "")
var domainLower = uri.Host.ToLower();
if(!allAnchorDomains.Contains(domainLower))
{
allAnchorDomains.Add(domainLower);
}
bool nahradit = domainsToReplaceAnchor.Contains(domainLower);
if (nahradit)
{
var lastDotIndex = href.LastIndexOf('.');
var extension = ""; //Path.GetExtension(href);
if (lastDotIndex != -1)
{
int questionMarkIndex = href.LastIndexOf('?');
if (questionMarkIndex != -1 && questionMarkIndex > lastDotIndex)
{
extension = SH.Substring(href, lastDotIndex - 1, questionMarkIndex-1);
}
else
{
extension = href.Substring(lastDotIndex);
}
}
if (extension != "")
{
if (!allAnchorExtensions.Contains(extension))
{
sampleUriByAnchorExtension.Add(extension, href);
allAnchorExtensions.Add(extension);
}
if (domainsToReplaceAnchor.Contains(domainLower) || SH.ContainsAny(href, ".JPG", ".Jpg", ".jpg", ".PNG", ".Png", ".png", ".JPEG", ".Jpeg", ".jpeg", ".GIF", ".Gif", ".gif", ".BMP", ".Bmp", ".bmp"))
{
string fileNameWithExt = seriesNumber.ToString() + "_" + imageNumber.ToString() + extension;
var http = "http://blog.sunamo.cz/i/" + fileNameWithExt;
string contentBeforeReplace = string.Copy(originalContent);
originalContent = originalContent.Replace(href, http);
if (contentBeforeReplace != originalContent)
{
try
{
webClient.DownloadFile(href, Path.Combine(targetFolder, fileNameWithExt));
}
catch (Exception ex)
{
Debug.Print(ex.Message);
}
imageNumber++;
}
}
}
else
{
Debug.Print("Link " + href + " had no extension");
}
}
}
//
}
foreach (var item4 in htmlEntityToChar)
{
if (originalContent.Contains(item4.Key))
{
originalContent = originalContent.Replace(item4.Key, item4.Value);
}
if (item.Title.Contains(item4.Key))
{
item.Title = item.Title.Replace(item4.Key, item4.Value);
}
}
//-Remove the opening and closing div
//-.Substring(5, cPuvodni.Length - 11)
item.content.nonVerbose = originalContent;
}
Debug.Print("ALL IMG DOMAINS");
foreach (var item in allImageDomains)
{
Debug.Print(""" + item + "",");
}
Debug.Print(Environment.NewLine);
Debug.Print(Environment.NewLine);
Debug.Print("ALL ANCHOR DOMAINS");
foreach (var item in allAnchorDomains)
{
Debug.Print(""" + item + "",");
}
Debug.Print(Environment.NewLine);
Debug.Print(Environment.NewLine);
Debug.Print("ALL IMG EXTENSIONS");
foreach (var item in allImageExtensions)
{
Debug.Print(""" + item + "",");
Debug.Print("Uri: " + sampleUriByImageExtension[item]);
}
Debug.Print(Environment.NewLine);
Debug.Print(Environment.NewLine);
Debug.Print("ALL ANCHOR EXTENSIONS");
foreach (var item in allAnchorExtensions)
{
Debug.Print(""" + item + "",");
Debug.Print("Uri: " + sampleUriByAnchorExtension[item]);
}
Debug.Print(Environment.NewLine);
Debug.Print(Environment.NewLine);
cmdSaveAllPostsAsBlogServiceExportFile_Executed2(excludeContainingInTitle);
NewStatus("All images were downloaded and the export file was created with them.");
}Now I am off to rework the posts from Windows 8 Apps Controls for my website sunamo.cz, and then I will delete both blogs on Blogger :).
EDIT the day after (November 29, 2014):
Because I found out that the code samples were not displaying correctly, I had to change, delete and upload everything all over again. So far, though, the few pages with snippets in various languages are working, so hopefully everything should work :).
All the images are filled in too, from 0 to 1101 for the old blog and similarly for the new one. Previously, when the application hit an image returning a 404 error, it did not download it, but the image counter was still incremented.